Vector Database Architecture, Scaling, and Real-Time Indexing
The production contract: correctness before performance
Most teams start a vector database design by comparing HNSW, IVF, and disk-oriented indexes. That is usually too early. An index is a mechanism, not a requirement, and choosing the mechanism before defining what the system must guarantee is the most common reason architectures that work cleanly in a proof of concept become unpredictable under real load.
A structural engineer does not pick steel, concrete, or timber and then figure out what the building needs to withstand. The design starts with occupancy, wind, seismic zone, and fire code - the material choice falls out of those constraints almost mechanically. Vector database architecture works the same way. HNSW, IVF, DiskANN, sharding, and replication are materials. The production contract is the load spec.
The contract has to define more than expected scale. It has to define what the system means by a successful write, a complete query, an authorized result, an acceptable stale read, and a recoverable failure. Without those definitions, every component can behave exactly as its local design intends while the system as a whole violates what the application assumed was true.
The workload envelope
The workload envelope describes the range of conditions the retrieval system must keep its guarantees under - sized to the planning horizon, not to the smaller, cleaner system that exists on launch day.
The term is borrowed deliberately from aviation. An aircraft is not certified because it can hit a particular top speed. It has to remain controllable across every combination of speed, altitude, weight, and turbulence it might encounter - a configuration that is safe at one corner of that envelope can be dangerous at another. Vector systems behave the same way. Corpus size, concurrency, mutation rate, filter selectivity, and tenant skew cannot be sized independently, because production will hand you every combination of them at once, usually at the worst possible time.
To stay concrete, picture two systems. The first serves a governed archive of legal and regulatory filings - steady inflow, mostly immutable, every record reconstructible from an authoritative source. The second serves memory for a production agent - continuous writes, permissions that can change mid-session, memories that range from minutes-relevant to months-relevant. At the level of "store embeddings, run nearest-neighbor search," they look identical. Their operating envelopes are close to opposites. Neither profile below is a fixed law of either domain - a regulatory change can make the archive intensely hot overnight, and an agent's durable preferences can stay warm for months. Treat them as illustrative pulls in different directions, not permanent labels.
Logical live set, physical population, and deployed footprint - three numbers, not one. The application sees the logical live set: records that should currently be retrievable. The index sees something larger: the physical population, which adds tombstoned nodes, superseded versions, and segments mid-compaction. The cluster is larger still - the deployed footprint multiplies that physical population across every replica, region, and snapshot. Think of a warehouse. The sales system reports a million items available - that's the logical live set. Returned stock, damaged pallets, and inventory awaiting write-off still occupy shelf space and slow down picking - that's the physical population. Operating three regional warehouses holding copies of all of it is the deployed footprint. In the archive, the first two numbers stay close - little gets deleted. In agent memory, they diverge fast, because expired observations sit as tombstones until compaction reclaims them. The gap between logical and physical is a production signal on its own: a widening gap means compaction is falling behind, well before anything else tells you that.
The real memory bill, not the encoding estimate. vector_count × dimensions × bytes_per_element prices the vector array. It says nothing about graph edges, metadata indexes, allocator overhead, write buffers, and compaction headroom - which routinely outweigh the vectors themselves, and which replication then multiplies again.
Temperature, described as a distribution, not a label. Some vectors get hit constantly; most don't. This governs whether a cache does anything useful and whether a disk-oriented index stays inside its latency budget. The archive might run cold and even - until active litigation makes one narrow slice intensely hot. Agent memory usually runs hot on recent writes, but durable facts and user preferences can stay warm indefinitely. What the contract needs isn't "hot" or "cold" as an adjective - it's what fraction of traffic concentrates in the hottest slice, and how fast that slice moves. Average QPS hides the same failure: a service comfortably averaging 1,000 QPS can fall over during a five-second burst to 5,000, and one query touching a single shard costs nothing like one that fans out across dozens of partitions.
Mutation as its own workload. A library catalogue can be reorganized on a slow, periodic schedule and nobody notices. An airport departure board is only useful if it reflects right now - a five-minute lag changes its meaning entirely. The archive behaves like the catalogue: optimize for stable structure, infrequent writes. Agent memory behaves like the departure board: it is being rewritten, expired, and re-permissioned continuously, by the same system serving live queries against the same data. Insert rate alone doesn't capture this - replacing a vector, flipping one access-control field, and bulk-loading historical data each stress a different part of the system, and the envelope needs to name each one.
Filter selectivity as a range, not an average. The same physical index might see a query spanning the entire corpus and, a moment later, one scoped to a single user's last hour of activity - a swing from hundreds of millions of eligible vectors to a few dozen. What the system needs isn't the average selectivity; it's how often each end of that range shows up, because each end favors a different execution plan - the subject of its own section later in this chapter.
Tenant skew and geography. Tenant count alone says nothing. Ten evenly-sized tenants partition predictably by almost any method. A thousand tenants where a handful account for most of the data create hot shards and noisy-neighbor pressure no matter how correct the partitioning logic is. Data residency and regional latency requirements can decide physical placement before index performance is even part of the conversation.
RTO and RPO - and precisely whose data they cover. Recovery time objective is how long the system can stay degraded. Recovery point objective is how much acknowledged data can be lost. The archive's index can often tolerate a loose RPO, because it's a derived representation - if source documents and ingestion checkpoints are durable elsewhere, the index rebuilds. That does not mean the underlying legal data tolerates loss; it means the vector subsystem specifically is recoverable. Get this scope wrong and you'll relax a durability guarantee on the wrong layer. Agent memory has less room here - if the last hour of observations exists only in the memory service, losing it silently erases part of what the agent believes has happened, and it may repeat completed work or reason from a gap it doesn't know is there.
The envelope isn't a spreadsheet of maximum values to hit. It's the territory inside which retrieval, state, and authorization correctness all have to keep holding. A system tuned for the archive will misbehave against agent-memory traffic. A system built for continuous agent memory will impose needless complexity and cost on a mostly-immutable archive. Filling this out honestly - before an index choice makes the decision for you by default - is what the rest of this chapter assumes you've done.
| Dimension | What to specify |
|---|---|
| Logical live set → physical population → deployed footprint | how far apart, and why |
| Memory driver | vectors, or graph + metadata + replicas |
| Hottest slice of traffic | what % of queries, how fast it shifts |
| Mutation types | insert / replace / expire / re-permission - separately |
| Filter selectivity range | narrowest and broadest cases seen, not the average |
| Tenant skew | top-N tenants' share of data and traffic |
| RTO / RPO, scoped | which layer specifically - index, or source of truth |
Searchable visibility latency
Chapter 2 defined Mean Time to Index (MTTI) - the delay between a source document changing and its new embedding being computed. This chapter needs a related but distinct number, because MTTI stops the moment the vector exists. It says nothing about whether that vector is actually findable yet.
Searchable visibility latency is the time from the database accepting a write to the point at which an eligible query is guaranteed to observe it, under the system's stated consistency model. A write moves through several distinct states on its way there, and a single "write succeeded" response can be quietly concealing which one it has actually reached:
Write accepted
      ↓
Durably recorded (safe, but not yet findable)
      ↓
Visible in the local mutable index
      ↓
Metadata / authorization fields applied
      ↓
Replicas synchronized
      ↓
Visible through the query path the caller actually uses
Each arrow can take a different amount of time, and a write can sit at any one of these stages while the caller believes it already reached the last one.
The everyday version of this is depositing a check. The bank accepts the deposit and records it durably the moment you hand it over - but the funds aren't usable for every purpose immediately. "Deposit accepted" describes persistence. It doesn't describe availability. A vector database acknowledgment carries the same ambiguity: success might mean the write reached a durable log, or that the primary node can find it, or that a quorum of replicas has indexed it. Unless the contract names which one, the application has no way to know what it's actually allowed to assume.
For an agent, this ambiguity is not academic. An agent that creates a task, writes it to memory, and immediately searches for it before deciding what to do next has no way to distinguish "that write failed" from "that write hasn't propagated yet" - both look identical from where it's standing: nothing came back. It may conclude the task never got created and make it again, or repeat a tool call it already completed. The data was never lost. The system still behaved incorrectly, because searchability is what the agent actually reasons from, not durability.
This is why interactive agent state usually needs a genuine read-your-writes guarantee, not just a low average indexing latency. That guarantee doesn't require the whole distributed index to synchronize before acknowledging the write - it can come from a session-local overlay, routing the agent's next read to the replica that took its write, or merging durable-but-not-yet-indexed records into the result set. The implementation is flexible. What has to stay fixed is the application-visible contract.
Not every mutation deserves the same visibility target - and the two directions carry opposite risk. Making new content findable is a positive propagation problem: the system is adding something the caller should now be able to see. Revoking access, deleting a record, or marking something superseded is an invalidation problem: the system has to stop returning something that may already be sitting in multiple indexes, caches, and replicas. A slow insertion produces an incomplete answer. A slow revocation produces an information leak - the caller sees something they are no longer supposed to see, at the exact moment someone decided they shouldn't. These are not the same severity of mistake, and a mature contract sets separate objectives for each: authorization revocations, legal holds, and workflow-state transitions typically need a tighter propagation guarantee than ordinary content ingestion, precisely because the failure mode on the invalidation side is worse.
Measure searchable visibility as a percentile, not a mean - a 200ms average can hide a tail where a small fraction of writes stay invisible for several seconds, and that tail is exactly where duplicate actions and stale-access incidents come from. Segment the measurement by workload class: a historical backfill can tolerate minutes of delay; a memory written mid-session usually can't; a workflow-state transition that prevents a repeated irreversible action needs the tightest guarantee of all. And be specific about whose visibility you're promising - a write might be visible in the writer's own session immediately, visible to the rest of the region within a defined percentile, and only eventually visible cross-region. "Searchable within two seconds" is not yet a contract. It becomes one once it names the query path, the replica scope, and whether the guarantee still holds during replica lag or rebalancing - not just during a healthy steady state.
A contract specific enough to build against might read: a memory written during an agent session is visible to that session's own subsequent queries immediately; visible to all replicas in the local region within 500ms at P99; and propagates cross-region under a looser eventual target. Authorization revocations are enforced synchronously at the trusted query boundary regardless of how far background index structures have caught up. That last clause matters more than it looks - it's what keeps a slow-to-propagate index from ever being the thing standing between a caller and access they no longer have.
Three independent forms of correctness
A vector database is not correct because it returns results quickly, or even because the nearest neighbors are mathematically accurate. Production correctness has three independent dimensions, and a failure in any single one makes the result wrong - regardless of how well the other two performed.
Take a concrete case: an employee asks an enterprise agent, "What is the current escalation policy for a Severity 1 incident?" The corpus holds three closely related documents - the current policy, last year's superseded version, and the current policy for a restricted business unit the employee has no access to. A correct system has to do more than find documents about escalation policies. It has to find the right policy, confirm that version is still valid, and enforce the employee's access scope. That gives three separate obligations, and this one query is enough to fail any of them independently.
Retrieval correctness - did the system find the evidence that actually answers the question? This is the familiar nearest-neighbor problem, but production never lets you evaluate it inside an isolated ANN benchmark. The query passes through routing, shard selection, replica selection, metadata planning, vector search, refinement, and cross-shard merging before a final result exists - and a local index can report excellent recall while the distributed system still misses the right document entirely. The router might exclude the shard holding it. A narrow filter might sever the graph path that leads to it. A timeout might drop one shard's contribution silently. Retrieval correctness is an end-to-end property of the whole path, not a number one index reports in isolation - the subject of the next section.
State correctness - does the evidence retrieved reflect what's true right now, not what was true when it was written? The system can retrieve the single most semantically relevant escalation policy in the entire corpus and still be wrong, because that document was superseded ten minutes ago. It's the nearest neighbor in embedding space and the wrong answer in time. Picture a navigation system computing the mathematically optimal route from yesterday's map - the path is perfect relative to the data it has, and useless if the bridge on that route closed this morning. Vector retrieval fails the same way: a result can be highly relevant and precisely ranked while describing a world that no longer exists. State correctness depends on searchable visibility, version selection, replica freshness, and deletion semantics - the difference between "closest record" and "currently valid record."
Authorization correctness - is the caller actually permitted to see this at all? This has to be enforced by trusted infrastructure, full stop. The agent, the prompt, and the reranker are relevance mechanisms, not security boundaries - telling a model not to repeat restricted information is not access control, and by the time unauthorized content has reached the model, the retrieval system has already failed. The guarantee covers more than the document text itself: identifiers, metadata, scores, excerpts, and even result counts can leak information about restricted data. One implementation nuance worth naming: this doesn't require every unauthorized vector to be excluded from all internal graph traversal. A node the caller can't see may still be structurally necessary as a waypoint on the path to one they can - excluding it outright can sever connectivity and cost you recall for no security benefit. The actual boundary is not the traversal itself. It's the point where information becomes observable outside the trusted retrieval system. What happens inside that boundary during navigation is an implementation detail; what crosses it is not.
These three are independent, and the Sev-1 example shows exactly why. A system can find the current, correct policy and hand it to someone in the restricted unit - retrieval and state correct, authorization failed, and now it's a security incident, not a quality bug. It can enforce authorization flawlessly and confidently return last year's superseded version - authorization and retrieval correct, state wrong, and the employee now follows an outdated process with total confidence. It can have the current, authorized version sitting in the corpus and simply never surface it because the query got routed to the wrong shard - state and authorization correct, retrieval wrong, and the agent never even knew the right answer existed.
The relationship is conjunctive, not additive - closer to multiplication than addition:
production_correctness = retrieval_correct × state_correct × authorization_correct
Any single zero collapses the whole result to zero. Two out of three is not partial credit - it's a specific kind of production failure, and each combination fails differently: wrong evidence is an incomplete answer, stale evidence is confident misinformation, unauthorized evidence is a security incident. The rest of this chapter is the architecture that keeps all three multiplying out to one at the same time, while the corpus keeps changing, traffic goes uneven, and pieces of the infrastructure fail. Every design choice from here forward is worth running through the same test: does this improve retrieval correctness, state correctness, or authorization correctness - or does it quietly trade one away to improve another?
Correctness during degradation
A contract that only describes healthy operation is half a contract. The guarantees that actually matter are the ones that still mean something after something has broken.
Say a query normally searches eight shards and one goes unreachable. The system has real options - wait for another replica, retry elsewhere, fail the request outright, or answer using the seven shards that responded. Each of those can be the right call depending on the workload. The one option that is never acceptable is the one nobody chose on purpose: quietly answering with seven shards' worth of evidence and presenting it as if all eight had been searched.
Picture an operations agent checking whether a customer already has an open incident, so it doesn't file a duplicate. The one relevant record happens to sit on the shard that's down. Seven shards come back empty, and the system reports "no matching incident." There are two very different things that could be true here - no incident exists, or part of the corpus couldn't be searched - and if the response doesn't say which one happened, the agent can't tell them apart. It may go ahead and open a duplicate incident, or kick off a redundant remediation, entirely because a database that was technically still up returned an answer it shouldn't have been confident about.
This is the difference between a service being available and a result being complete. The API call succeeded. The evidence behind it wasn't enough to support the conclusion the agent was about to draw from it - the same way a lab reporting nine results out of ten ordered tests should never let a doctor read the missing tenth as "normal." Missing is not the same claim as negative, and a retrieval system needs to preserve that distinction just as carefully.
In practice, this means every response needs to carry a small amount of information about how it was produced - not the internal topology of the database, just enough for whatever is calling it to know: did the full intended search space get covered, was a fallback replica used, did any of the data involved look stale, was this served under degraded conditions at all. Once that's explicit, the caller gets to decide what to do with an incomplete answer, instead of the database silently deciding for it. An assistant answering a general question might proceed anyway with a caveat. An agent about to move money, revoke access, or change something in production should probably refuse to act until it has the full picture.
Completeness and freshness are also two separate axes, not one, and failures can hit either independently:
| Fresh | Stale | |
|---|---|---|
| Complete | normal operation | full corpus searched, on old data |
| Incomplete | current data, partial corpus | worst case - both wrong |
Which combination is tolerable depends entirely on what the agent is about to do with the answer. A system generating a casual recommendation can probably live with slightly stale context. An agent checking whether a step already ran needs current state above almost everything else. An agent making a security-sensitive decision needs both - full coverage and fresh data - before it should act at all.
The same thinking applies on the write side. If the durable log is fine but indexing has fallen behind, the database hasn't lost anything - writes keep succeeding, nothing is at risk. But from the agent's point of view, something it just wrote is temporarily invisible, which is functionally the same problem as data loss for anything reasoning in real time. Compaction falling behind is a quieter kind of degradation, and it's worth walking through step by step. Compaction is the background cleanup that permanently removes deleted and outdated entries - until it runs, those entries just sit there as tombstones. When compaction lags, tombstones build up faster than they're cleared, so the index physically grows larger than the data it's actually supposed to hold. A bigger index means less of the useful part fits in fast memory, so more queries end up reaching slower storage than they should. Old graph connections that still point to deleted entries also stay in place longer, which makes the graph itself slower and less efficient to search. None of this shows up on a latency dashboard right away - your P99 can look completely healthy for weeks while the system is quietly using up the safety margin it needs for the next traffic spike or node failure.
This is why a production system needs three states, not two: healthy, degraded, and unsafe to continue. Degraded doesn't mean broken - it means one or more guarantees have weakened in a way that's known and bounded. Unsafe means continuing to accept work would break a guarantee something downstream actually depends on. At that point, the right move can be to push back or refuse new work rather than stay available at any cost - which runs against the usual distributed-systems instinct to keep serving traffic no matter what. But for a system an agent can take irreversible actions from, a confident wrong answer is worse than no answer. Sometimes the correct behavior is to fail closed.
Writing the contract as an engineering artifact
None of this is useful sitting only in someone's head. A production contract has to be precise enough that a different engineer can turn it directly into tests, dashboards, alerts, and incident playbooks without ever asking the original author what they meant.
"Memories become searchable quickly" is not a contract - it's a hope. A real one names a percentile target, says whether it applies to the writer's own session or every replica everywhere, and states what happens to that number during a failover. "Retrieval has high recall" is equally empty on its own - high against which evaluation set, which filter conditions, which candidate depth, and what happens to that number when a shard goes down. "Tenants are isolated" needs to say where the enforcement actually happens, what infrastructure is physically shared underneath it, and what the blast radius looks like if that enforcement ever fails. Even deletion needs this precision: "deleted immediately" might only mean the record disappears from search results, while the vector itself still sits in a replica, a snapshot, and three backups. Disappearing from results and being physically gone are two different promises with two different deadlines.
A working contract connects what the application expects to something the system can actually be measured against:
what the application expects
        ↓
the guarantee the system makes
        ↓
a measurable target
        ↓
something that tracks whether it's being met
        ↓
what happens when it isn't
Here's the same chain, filled in end to end with a real example: agent memory.
What's needed: an agent should never repeat an action because it couldn't find a memory it wrote seconds ago.
What gets promised: within the same session, a write is guaranteed visible to the very next read. No exceptions - this is one case where the target is 100%, not a percentile, because it's scoped to a single session rather than spread across replicas and regions.
The number that proves it: every same-session read that fails to see a write it should have seen counts as a violation, tracked continuously.
What watches that number: an alert fires the moment a single violation happens - this guarantee is strict enough that "mostly working" isn't good enough.
What happens when it breaks: the agent falls back to a temporary local copy of what it just wrote, or waits briefly and checks again, or - if it's about to do something with real consequences, like moving money or deleting a record - refuses to act at all until it can see current state.
That's the whole chain filled in: what's needed, what's promised, the number that proves the promise, what's watching that number, and what happens the second it's broken. Retrieval completeness, authorization, deletion, and replica freshness all deserve this same treatment - a real number and a real answer for what happens when that number gets missed, not just a description of the guarantee in words.
This also changes what a design review actually argues about. Instead of debating whether HNSW is "better" than DiskANN in the abstract, the real question becomes whether a proposed architecture satisfies the contract under the workload and failure conditions already defined. Index choice, sharding, replication, and filtering stop being isolated technology preferences and become consequences of guarantees someone already wrote down.
Everything that follows in this chapter - the read path, index selection, data placement, the write path, deletions, filtered search, multi-tenancy, and observability - exists for one reason: keeping these guarantees true while the corpus keeps changing, traffic goes uneven, and pieces of the system inevitably fail.
The distributed read path and the retrieval error budget
An ANN benchmark answers a narrow question: given a query vector and a known set of vectors, how often does the algorithm find the true nearest neighbors? Production has to answer a harder one: did the evidence the agent actually needed survive the entire trip from request to context?
Those are not the same measurement, and the gap between them is where most retrieval quality actually gets lost in a real system - not inside the ANN algorithm itself.
Take a concrete case: an enterprise agent is asked, "What did we decide about payment fallback for Merchant X after last week's incident?" The right answer genuinely exists in the corpus. That alone does not mean the agent will see it. Before the agent gets an answer, the request typically passes through something like this:
Agent request
     ↓
identity + authorization scope
     ↓
query embedding
     ↓
shard routing
     ↓
replica selection
     ↓
metadata + time-based filtering
     ↓
local ANN search
     ↓
candidate refinement
     ↓
cross-shard merge
     ↓
reranking / deduplication
     ↓
context delivered to the agent
Every arrow on that list is a place where the effective search space can shrink, and the ANN index in the middle of it is only one component of the system's actual recall. This is the idea behind the retrieval error budget: retrieval quality gets spent across the whole path, not just inside the algorithm most benchmarks measure.
The search space narrows before vector search even starts
The first cut usually happens before a single distance gets computed. The caller's identity determines which tenant, business unit, or security scope the query is even allowed to search - agent state can narrow it further, to one workflow or one time window. For the Merchant X query, the physical database might hold hundreds of millions of vectors while this specific caller is only entitled to search a small slice of them. That slice is the eligible corpus, and getting its boundary wrong fails in two different directions: too broad and it's a security incident, too narrow and it's a retrieval failure that looks exactly like the document doesn't exist. The correct document can be sitting in the corpus, the embedding can be excellent, and the local index can score perfect recall on the vectors it was given - and the system can still return nothing, because the right evidence was excluded before the search ever began.
This matters for how you measure recall, not just how you serve it. If an offline benchmark searches the whole valid corpus while production always searches a narrower, dynamically-built tenant-and-time scope, the two numbers are answering different questions and shouldn't be compared as if they're the same metric.
Routing can spend recall before ANN gets a turn
Once the eligible corpus is too large for one machine to search directly, something has to decide where to look. The simple approach - fan every query out to every shard that might have eligible data - keeps full coverage but gets expensive fast as shard count grows, and gets slower every time one shard is a little behind the rest. The alternative is pruning: a coordinator picks the shards it believes are worth searching and skips the rest, which quietly turns routing into its own approximate search stage.
Say the corpus is split into fifty partitions and the router picks the five most promising ones. If the router guessed right, searching five instead of fifty is a large win. If the relevant evidence actually lives in partition six, no amount of tuning the ANN search inside those five partitions will find it - the recall was already spent at the routing step, before the local index had a chance to do anything.
This gives routing its own metric worth tracking separately: routing recall - of the true top-k relevant documents for a query, what fraction actually land inside the partitions the router chose to search? Defining it this way, as a set rather than a single best-answer hit, is what lets it compose directly with Recall@k downstream instead of measuring something slightly different that only looks similar.
A system can post 99% local ANN recall and still only 94% routing recall - and the second number is a ceiling the first one can never repair, no matter how well-tuned the index underneath it is.
Replica selection decides which version of reality gets searched
Routing decides where a query runs. Replica selection decides which state of the data it sees when it gets there - and this is exactly where the read path meets the searchable-visibility contract from earlier in this chapter.
Say the payment-policy document was updated thirty seconds ago. One replica has already indexed the update; another hasn't caught up yet. A load balancer optimizing purely for speed might correctly pick the faster replica - and hand back the wrong version of the truth. The ANN algorithm didn't fail here. It searched exactly what was available to it. The problem is that the query landed on the wrong snapshot of reality. This is why replica freshness in an agentic system can't be treated as a pure infrastructure metric - if part of your contract is read-your-writes or bounded staleness, that requirement has to reach into replica selection directly, not be left to a load balancer that only knows about latency.
This is worth naming precisely: the read path just lost state correctness, not recall. The document wasn't missed - it was found, correctly, and it was still the wrong answer. Section 1 drew this exact line between retrieval correctness and state correctness, and the read path is where that distinction stops being theoretical: routing and ANN search mostly put retrieval correctness at risk, while replica selection mostly puts state correctness at risk. Not every stage on this path is spending the same currency.
Filtering changes the shape of the search problem
After routing, structured conditions narrow things again - tenant match, status not-superseded, effective date, caller's visibility scope. It's tempting to think of these as an ordinary database WHERE clause bolted onto vector search. At scale they're more consequential than that. A filter that still leaves 80% of a partition eligible barely changes anything - the graph is still dense enough to traverse normally. A filter that leaves 0.1% eligible can change the shape of the problem entirely, because the graph was built around vector proximity, not around whatever narrow slice one particular metadata predicate happens to select. Filtered search has become its own query-planning problem for exactly this reason - covered in full in its own section later in this chapter. The takeaway for the error budget here is simpler: recall measured without any filter applied does not describe recall under the filters your production traffic actually uses.
ANN recall is conditional recall
Only now - after scope, routing, replica, and filter have all already had their turn - do we reach the part most vector-search benchmarks actually measure. Within whichever shard got selected, against whichever replica state got searched, under whatever predicates applied, the ANN index tries to recover the true nearest candidates. This is an approximation by design: more graph exploration, more partitions probed, or a wider beam generally buys a better chance of finding the true neighbors, at the cost of more latency or I/O. The exact knob differs by index family; the trade is the same everywhere.
The right way to think about what this number actually measures: given that the correct shard was picked, the right replica was searched, and the record survived filtering - what's the chance ANN puts it in the candidate set? That's a genuinely useful number. It is not end-to-end retrieval recall, and treating it as if it were is the single most common measurement mistake in production retrieval systems.
Merging across shards - and a correction worth making precisely
Once several shards each return candidates, a coordinator has to build one global ranking. There's a common misunderstanding worth clearing up here. If every shard holds disjoint data, every shard performs exact search, and every shard returns its own true top-k, the coordinator has everything it needs to reconstruct the exact global top-k - a global top-k result can never contain more than k items from any single shard, so nothing is lost by only asking each shard for k. Sharding by itself does not force anyone to over-fetch.
Production systems oversample anyway, but it's worth being precise about what oversampling actually fixes, because it's easy to conflate two different problems that need two different knobs.
If the graph traversal never visits the region of the graph where a strong candidate lives - a genuine traversal miss - asking the shard for more results afterward does nothing. The candidate was never found; there's nothing to return more of. Fixing a traversal miss means spending more search effort: a wider efSearch in HNSW, more probed partitions in an IVF index, a wider beam. That's a different lever from the one most people reach for first.
Oversampling means asking each shard to hand back more candidates than you'll actually use - say 40, when the final answer only needs 10. It fixes a different problem than search effort does: not candidates the traversal missed, but candidates it genuinely found that a later step might still drop or reorder. A few concrete examples of that later step: recomputing an exact distance and finding the cheaper estimate used earlier was slightly off, applying a filter that removes something ineligible, collapsing near-identical duplicate results into one, or simply losing out in the final ranking because one shard didn't send over enough options to compete fairly against the others. Oversampling gives each of these a wider pool to work with before anything gets finalized.
Back to the audition: search effort is how closely the first-round judges pay attention. Oversampling is simply how many acts get invited to the second round once that first look is done. Both matter, but they solve different problems - paying closer attention finds acts that would have otherwise been missed entirely; inviting more people to round two just gives round two more room to pick correctly among whoever showed up.
Either way, oversampling and deeper search both cost something real - more compute, more network transfer, more work for whatever reranks the result downstream. Both belong in the latency budget as much as the recall budget, because they're spending against both at once.
Exact refinement fixes ordering, not omission
Many production indexes search over a compressed or approximate representation first, then compute precise distances for a smaller shortlist. This is a genuinely good architecture - full-precision comparison only gets spent on candidates that already survived the cheap stage - but it's easy to overestimate what it can fix. Exact refinement can correct the order of candidates that made it through. It cannot correct a candidate that never made it through at all. If the right document was lost at routing or at the approximate ANN stage, there is nothing left downstream to rescore. The same limit applies to a reranker later in the pipeline, no matter how sophisticated it is - a cross-encoder or an LLM reranker can judge relevance far better than cosine distance, but its judgment only ever covers whatever the earlier stages handed it. Every stage in this path is a funnel: later stages can clean up what remains, but nothing restores what already fell out.
Deadlines can quietly become recall policy
Distributed retrieval has one more failure mode an isolated benchmark never surfaces: stragglers. Say a query fans out to sixteen shards, fifteen respond in 20ms, and one takes 80ms against a 50ms deadline. Waiting protects coverage and blows the latency budget. Returning at the deadline protects latency and silently drops one-sixteenth of the intended search space. That timeout policy just became a recall policy, whether anyone meant it to or not - and this gets worse as fan-out grows, since end-to-end latency increasingly gets dictated by whichever single shard is slowest that moment, not by the average.
For a casual informational query, answering with fifteen out of sixteen shards might be perfectly fine. For an agent deciding whether an irreversible action has already happened, it might not be - which ties directly back to the degradation contract from earlier in this chapter. A deadline-induced drop in coverage has to be visible to whatever is calling the retrieval system. A partial answer must never be indistinguishable from "no evidence exists."
Putting the budget together
It's tempting to read every stage on this path as simply subtracting from one number - recall. That undersells what's actually being traded. Every design choice here spends against three things at once, not one:
Recall        - was the relevant evidence preserved at all?
Freshness     - did the search run against current state, not stale state?
Latency/cost  - what did preserving the other two actually cost?
The examples already on this page show all three in play, not just recall. Aggressive shard pruning trades recall for lower fan-out cost. A narrower ANN search beam trades recall for latency. Authorization scoping deliberately shrinks the search population - and that's not a loss at all, it's correctness working as intended, because a smaller correct population beats a larger population that includes evidence the caller was never supposed to see. Replica selection, as the earlier section showed, can preserve recall perfectly while losing freshness outright. Waiting out a straggling shard improves completeness at the direct cost of the latency SLO. None of these are the same trade, and treating them as if they all just subtract from one shared "recall budget" hides what's actually happening.
The deeper model, then: the distributed read path is where the system trades recall, freshness, completeness, latency, and cost against each other. The retrieval error budget describes how much loss of relevant evidence is acceptable - one axis inside that larger correctness envelope, not the whole envelope by itself.
The staged view below traces one specific axis through that envelope - whether relevant evidence survives to be discoverable at all. It's a recall model on purpose. Freshness is a separate currency, spent in different places (replica selection, chiefly), and it needs its own instrumentation rather than being folded into this same diagram.
relevant evidence exists
        ↓ inside the authorized scope?
        ↓ inside the partitions the router picked?
        ↓ present on the replica that got searched?
        ↓ still eligible after filtering?
        ↓ recovered by the approximate ANN search?
        ↓ survives refinement and merging?
        ↓ survives the deadline?
        ↓ reaches the agent
Resist the urge to treat this as simple subtraction - "98% ANN recall minus 1% routing loss minus 1% filtering loss equals 96% system recall" is a clean-looking equation that doesn't reflect how these errors actually behave. They're conditional and correlated in practice: the queries that route badly are often the same ones that also interact badly with filters and need the deepest graph search, which is exactly why adaptive systems that adjust partitioning and search parameters as conditions shift - rather than assuming one fixed operating point - are an active area of current research.
The practical takeaway matters more than any formula: instrument each stage separately, but judge the system end to end. Routing recall tells you if partition pruning is failing. Recall measured within each filter regime tells you if narrow queries are the ones regressing. Local ANN recall tells you if an index parameter needs tuning. Shard completion rate tells you how often deadlines are cutting off part of the search. Reranker rescue rate tells you how much weak upstream ordering is being fixed downstream. But the one number that actually matters is Recall@k measured at the exact boundary the agent consumes - under the same authorization, filtering, routing, and deadline conditions a real production request experiences, not the clean conditions of an isolated benchmark.
An ANN benchmark tells you how good an index can be under controlled conditions. The distributed read path tells you how much of that quality survives contact with reality - the difference between a car's rated top speed and what it actually does stuck in rush-hour traffic.
ANN index selection under real workload constraints
This section goes deep on four ANN index families - HNSW, IVF, product quantization, and DiskANN. If you've never worked with any of them, each one gets a one-sentence plain-English summary right where it's introduced, before the detailed mechanics. Read those first pass, then come back for the depth.
Approximate nearest-neighbor indexes all solve the same underlying problem.
Given a query vector q and a corpus containing N vectors, find the k vectors closest to q under the chosen similarity metric without comparing q against every vector in the corpus.
The exact solution is straightforward:
query vector
     ↓
compare against vector 1
compare against vector 2
compare against vector 3
...
compare against vector N
     ↓
sort distances
     ↓
return top-k
Nothing is approximate here. If the distance computation is correct, the returned nearest neighbors are correct.
The problem is the amount of work.
For N vectors of dimension d, a brute-force search performs work proportional to roughly N × d per query. Modern CPUs and GPUs can execute these operations extremely efficiently, which is why exact search should remain the baseline and should not be dismissed automatically for smaller collections, highly batched workloads, or cases where index-construction cost cannot be amortized. Current Faiss guidance still recommends a flat index when exact results are required or when the number of searches is too small to justify building a more complex index.
But once the corpus, query concurrency, or latency target makes scanning everything too expensive, the architecture must somehow avoid looking at most vectors.
That is what ANN indexing really is.
Every major ANN family introduces a reason to believe:
“The vectors I am not examining are unlikely to contain the answer.”
HNSW creates a graph that lets the search navigate toward promising neighborhoods without visiting the rest.
IVF divides the space into regions and searches only the regions most likely to contain the query’s neighbors.
Product quantization compresses vectors so that many more candidates can be compared cheaply.
DiskANN constructs a graph specifically so that navigation can cross an SSD-backed corpus with a small number of storage accesses.
The algorithms differ primarily in where they place the approximation and which resource they spend to compensate for it.
That is the right mental model for index selection.
HNSW: turn nearest-neighbor search into graph navigation
In one sentence: HNSW connects every vector to its neighbors like a road network, so a search can drive toward the right neighborhood instead of visiting every address in the city.
HNSW-Hierarchical Navigable Small World-is easiest to understand by temporarily forgetting vectors.
Imagine every location in a country connected only to nearby locations.
If you want to travel from Seattle to Miami but can move only between neighboring streets, the route requires an enormous number of hops. What you want is a mixture of connections at different scales: interstate highways for long-distance movement, state highways for regional movement, and local streets near the destination.
HNSW constructs something similar in vector space.
Each vector becomes a node in a proximity graph. Nodes connect primarily to vectors that are nearby under the similarity metric. On top of this base graph, HNSW builds progressively sparser layers containing fewer nodes. A vector is randomly assigned a highest layer, with the probability of appearing in higher layers decreasing exponentially. The resulting structure resembles a skip list: sparse upper layers provide long-distance navigation, while the dense bottom layer performs the detailed neighborhood search.
Conceptually:
Layer 3:         A ----------------------------- Z

Layer 2:         A -------- G -------- M ------- Z

Layer 1:         A -- C -- G -- J -- M -- R --- Z

Layer 0:         A-B-C-D-E-F-G-H-I-J-K-L-M-...-Z
This picture is intentionally simplified, but it captures the important idea. The search does not start by inspecting every node on the bottom layer. It starts in a sparse layer where a few long jumps can move it toward the query.
Suppose the query lies somewhere near node R.
At the highest layer, HNSW starts from an entry point and asks which neighboring node is closer to the query. It greedily moves toward that neighbor until none of the available neighbors improves the distance. It then drops down one layer and continues. Each lower layer offers increasingly fine-grained navigation.
Eventually the search reaches the dense base layer, where it performs a broader best-first exploration around the promising region it has reached.
That hierarchy is what gives HNSW its characteristic behavior: it spends memory constructing enough connectivity that the query can navigate toward its neighborhood without scanning the entire corpus. The original HNSW design explicitly uses this multi-layer graph with exponentially decreasing membership at higher layers.
The first important parameter is usually called M.
M controls roughly how many graph connections each node is allowed to maintain. The precise details vary between implementations and layers, but the intuition is stable.
With too few links, the graph is cheap but poorly connected. Search can become trapped in a locally good region that is not globally correct.
With more links, each node offers more possible directions. Navigation becomes more robust, particularly in complicated or clustered vector spaces, but the graph consumes more memory and construction work.
Current Faiss guidance, for example, exposes M directly as the major HNSW memory-versus-accuracy parameter and estimates graph storage on top of the raw vector representation.
The second important parameter is efConstruction.
When inserting a vector, HNSW itself has to perform a search to discover which existing nodes should become its neighbors. efConstruction controls how much candidate exploration is performed while building those connections.
A larger construction search generally produces a better-connected graph, but indexing becomes more expensive.
This is one of the reasons index build quality and query quality are coupled. A cheaply built graph cannot always be rescued by spending more query-time search later.
The third important parameter is efSearch, often shortened to ef.
At the bottom layer, HNSW does not simply follow one greedy path and stop. It maintains a candidate frontier containing promising nodes. efSearch controls how wide that frontier is allowed to become.
You can think of it as the difference between asking one person for directions and asking twenty.
With a small efSearch, the algorithm explores a narrow neighborhood and returns quickly. If the graph happened to guide it toward the wrong local region, the correct neighbor may never be visited.
With a larger efSearch, it explores more alternatives. Recall improves, but more graph nodes and vectors must be fetched and compared.
The important relationship is therefore:
larger efSearch
       ↓
more nodes explored
       ↓
higher probability of finding true neighbors
       ↓
more CPU + memory traffic
       ↓
higher latency / lower maximum throughput
This is ANN approximation in its clearest form.
The index has not changed. The system is changing how much uncertainty it is willing to tolerate per query.
That opens an interesting production possibility: efSearch does not necessarily need to be globally fixed.
A high-risk agent query may justify deeper exploration. A background recommendation query may tolerate lower recall in exchange for higher throughput. A query for which the first few results are overwhelmingly strong might terminate earlier than an ambiguous query whose candidate distances are tightly clustered.
A fixed efSearch for every query is convenient, but it assumes every query deserves the same search effort. In production, that is rarely true. Some queries fall into dense, unambiguous neighborhoods and converge quickly; others sit near cluster boundaries or have many nearly tied candidates and require deeper exploration to preserve recall. Recent research has therefore explored query-adaptive execution: terminating early when sufficient evidence has been found, or dynamically increasing search effort when the estimated recall is still below target. Systems such as HAKES and Quake are examples of this direction rather than prescriptions for a particular implementation.
That distinction matters at Principal Engineer scale.
The question is no longer merely:
“What should
efSearchbe?”
It becomes:
“Which workload classes deserve which point on the recall-versus-resource curve, and how do we detect when that curve has shifted?”
HNSW insertion explains its write-path behavior
Understanding how HNSW inserts a vector also explains why read-write workloads matter.
A new vector does not simply get appended to an array.
The graph must discover appropriate neighbors for the new node, select which connections to preserve, create links, and potentially modify neighbor lists of existing nodes.
Conceptually:
new vector
    ↓
search existing graph for candidate neighbors
    ↓
choose a diverse set of good neighbors
    ↓
attach new node
    ↓
update graph connectivity
The same graph is simultaneously being traversed by searches.
The exact concurrency mechanism depends on the implementation-locking, copy-on-write structures, mutable segments, batching, or background graph construction-but the fundamental issue does not disappear. Read traffic wants stable, cache-friendly graph traversal. Write traffic is changing that graph.
This is why a statement such as “HNSW supports incremental inserts” is insufficient for architecture selection.
The relevant question is what happens to p99 search latency and recall when production insert, update, and delete rates occur concurrently.
HAKES explicitly identifies construction cost and read-write contention as shortcomings of conventional graph-index deployments and proposes separating compressed candidate filtering from more expensive refinement in a distributed design. Its reported improvements are experimental rather than universal production guarantees, but the research reinforces the underlying systems problem: a graph that looks excellent under static query benchmarks can behave differently while continuously changing.
This distinction is particularly relevant for agentic systems.
A corporate knowledge corpus containing mostly immutable documentation is naturally friendly to HNSW. An agent-memory store that writes, expires, replaces, and re-permissions vectors continuously stresses a different part of the algorithm.
The same index family may still work for both.
The operating point will not be the same.
HNSW’s hidden resource is memory bandwidth
HNSW is often described as memory-heavy because the graph consumes RAM.
That is true, but capacity is only half of the problem.
The other resource is memory bandwidth.
Suppose the system uses 1,536-dimensional FP32 embeddings. One raw vector occupies:
1,536 dimensions × 4 bytes
≈ 6 KB
A query that causes the graph to examine thousands of vectors may move several megabytes of vector data through the memory hierarchy even though the arithmetic required to calculate each distance is relatively simple.
Under low concurrency, this can look excellent.
Under high concurrency, multiple searches compete for the same cache hierarchy and DRAM channels. Eventually, adding more CPU cores produces diminishing returns because the processors are waiting for vector data rather than arithmetic.
This is one reason graph ANN and brute-force vector arithmetic have different scaling characteristics. HNSW reduces the number of vectors examined but introduces irregular pointer-driven access through graph neighborhoods. CPU caches and prefetchers cannot always predict where the next node will live.
At sufficient concurrency, the important capacity metric becomes not only “queries per CPU core,” but “queries per unit of memory bandwidth.”
That observation will reappear when we discuss IVF and PQ, because they make a very different trade: their access patterns can be more regular and batch-friendly, which is one reason partition-and-scan approaches map well to GPU execution. Current Faiss support reflects this difference: IVF/PQ configurations are supported on GPU, while its HNSW implementation is CPU-oriented.
This is not an argument that IVF is inherently better than HNSW on GPUs.
It is a reminder that algorithmic structure determines hardware efficiency.
IVF: search the neighborhood, not the city
In one sentence: IVF sorts the whole corpus into neighborhoods ahead of time, so a query only has to check the handful of neighborhoods it's most likely to belong in, not the entire city.
IVF-Inverted File indexing-solves the same problem using a very different idea.
Instead of building connections between individual vectors, IVF divides vector space into regions.
Suppose this two-dimensional picture represents vectors:
        x x x
      x x x x

                         x x
                       x x x x

            x x
          x x x

                                  x x x
                                x x x x
The groups form natural clusters.
During index construction, IVF typically runs a clustering algorithm such as k-means and learns a set of representative vectors called centroids.
The space then looks conceptually like:
      [ C1 ]                [ C2 ]


                  [ C3 ]


                                [ C4 ]
Every database vector is assigned to its nearest centroid.
The index stores the vector identifier in the corresponding inverted list:
C1 → [v2, v8, v31, v77, ...]
C2 → [v1, v4, v13, v20, ...]
C3 → [v3, v7, v22, v41, ...]
C4 → [v5, v9, v18, v62, ...]
This is where the name inverted file comes from. Instead of asking which cluster a vector belongs to by scanning the corpus at query time, the index already maintains the reverse mapping from cluster to vectors.
When a query arrives, IVF first compares the query with the centroids.
Suppose centroid C3 is closest.
Instead of examining every vector in the database, the search opens the list attached to C3 and compares the query only with vectors stored there.
That is the approximation.
The search assumes:
“If the query lies close to centroid C3, its nearest neighbors probably live in C3’s partition.”
The problem is the word probably.
Imagine that the true nearest neighbor sits just across the boundary between C3 and C4.
Searching only C3 misses it.
IVF therefore usually searches several nearby partitions rather than exactly one.
The number of partitions is commonly called nlist, and the number searched for a query is nprobe. Faiss describes IVF in exactly these terms: the dataset is divided into nlist cells, vectors are stored in inverted lists associated with those cells, and a query searches only nprobe selected lists.
Conceptually:
nlist = 100,000 total regions

nprobe = 1
→ search only nearest region
→ cheap, highest boundary-miss risk

nprobe = 16
→ search 16 likely regions
→ more work, better coverage

nprobe = 256
→ search much larger part of space
→ still more work, typically higher recall
Faiss notes that a first-order estimate of the fraction of the database inspected is around nprobe / nlist, although real inverted lists are uneven and therefore the true scanned fraction varies.
This gives IVF a very different control surface from HNSW.
HNSW says:
“Navigate through the graph and decide how broadly to explore.”
IVF says:
“Partition the universe first and decide how many regions to open.”
Both avoid exhaustive search.
They place the first approximation at different locations.
nlist is not simply “more partitions is better”
A novice intuition is that more partitions must always improve performance because each list gets smaller.
That is only half true.
Increasing nlist reduces the number of vectors in each inverted list, but it also increases the number of centroids the system must manage and makes the partitioning more fine-grained.
If the partitions become extremely small, the query may need to probe many of them to avoid boundary misses.
There is therefore a balance:
few large partitions
→ cheap routing
→ lots of vectors scanned per partition

many small partitions
→ expensive / more complex routing
→ fewer vectors per partition
→ may require more probes for recall
The optimal point depends on dataset size, dimensionality, distribution, query batching, hardware, and recall target.
Current Faiss guidance scales IVF partition counts upward with dataset size and even recommends hierarchical or HNSW-based coarse quantizers at large scales because finding the relevant centroids can itself become a nontrivial search problem.
That is a useful example of an important production pattern:
ANN algorithms compose.
The architecture does not have to choose “HNSW or IVF.”
HNSW can be used to find the IVF centroids.
IVF can determine which portion of a collection should be searched before another ANN index runs inside the partition.
PQ can compress the vectors stored inside IVF.
Exact full-precision search can refine candidates returned by all of them.
Production architectures frequently look more like pipelines than mutually exclusive algorithm choices.
IVF learns the corpus, which means the corpus can outgrow the assumptions
HNSW primarily builds connectivity from the vectors inserted into the graph.
IVF explicitly learns a partitioning from training data.
That difference has operational consequences.
Suppose the original corpus contains embeddings from:
40% product documentation
30% support cases
20% architecture documents
10% operational runbooks
The trained centroids distribute themselves around that geometry.
Six months later, the same index contains:
10% original knowledge
90% short-lived agent memory
The vectors may now occupy very different regions.
Some inverted lists can become disproportionately large. Others may receive almost no new vectors. Query traffic may concentrate on a small fraction of partitions.
The index still functions.
But the cost model assumed at training time has changed.
One partition may now contain ten times as many vectors as another, so “search eight lists” no longer corresponds to a predictable amount of work. Hot partitions may dominate CPU and cache consumption. The same nprobe can produce dramatically different latency depending on which lists a query happens to touch.
This is where partition balance becomes a production metric rather than an indexing detail.
Static partitioning assumes that the corpus and query distribution remain close to the conditions under which the index was originally tuned. In production, that assumption often breaks: new data can concentrate in particular regions of the embedding space, query traffic can become skewed, and previously balanced partitions can turn into hot spots. At that point, the same partition count and probe strategy may no longer provide the same latency–recall tradeoff.
This has motivated research into adaptive partitioning and adaptive query execution, where partitions can be reorganized as the data distribution changes and the amount of search work can vary with the query rather than remaining globally fixed. Quake is one recent research example of this direction.
The architectural takeaway is broader than any specific system: if an index depends on a learned or static partitioning of the corpus, production needs a way to detect when that partitioning no longer matches the data and traffic it is serving.
Product quantization: stop carrying every coordinate at full precision
In one sentence: product quantization shrinks every vector down to a tiny compressed code, so you can compare far more candidates using the same amount of memory and bandwidth - at the cost of a small, controllable amount of precision.
IVF reduces the number of vectors that need to be examined.
Product quantization attacks a different cost: the size of each vector that gets examined.
Suppose an embedding has 768 FP32 dimensions.
Its raw representation requires:
768 × 4 bytes = 3,072 bytes
Now imagine splitting that vector into 96 blocks, each containing eight dimensions.
768-dimensional vector

[8 dims][8 dims][8 dims] ... [8 dims]
   1       2       3            96
For each eight-dimensional subspace, PQ learns a small codebook of representative subvectors.
If each codebook contains 256 representatives, one byte is enough to identify which representative best approximates each subvector, because one byte can encode 256 possibilities.
The original 3,072-byte vector can now be represented approximately by 96 one-byte codes:
Full FP32 vector:       3,072 bytes
PQ representation:        96 bytes
That is roughly 32 times smaller in this illustrative configuration.
The original PQ work describes exactly this idea: split a high-dimensional space into multiple lower-dimensional subspaces, quantize each subspace independently, and represent the complete vector using the combination of those compact subspace codes.
The remarkable part is that search does not need to reconstruct every vector completely.
For each query subvector, the system computes its distance to every centroid in that subspace’s codebook. Those distances form small lookup tables.
Suppose database vector x has PQ code:
[17, 204, 3, 88, ...]
Instead of loading all of x's floating-point coordinates, the search looks up:
distance(query_subvector_1, codeword_17)
+
distance(query_subvector_2, codeword_204)
+
distance(query_subvector_3, codeword_3)
+
...
The result approximates the distance between the query and the original vector.
This is known as asymmetric distance computation when the query remains uncompressed while database vectors are represented by PQ codes. The original PQ work found this more accurate than compressing both sides.
From a systems perspective, this is powerful because the database can evaluate many more candidate vectors from cache or memory for the same bandwidth.
But something has been lost.
The original vector was replaced by a nearby representative in each subspace.
That difference is quantization error.
If two candidates are far apart, this error may not matter.
If they are extremely close, the compressed representation can reverse their ordering.
The real distances might be:
Document A = 0.214
Document B = 0.218
while PQ estimates:
Document A = 0.221
Document B = 0.216
Now the approximate search ranks B ahead of A.
This is why compression belongs in the retrieval error budget.
Why OPQ exists
Ordinary product quantization makes a strong assumption: splitting the dimensions into fixed groups produces subspaces that are reasonably easy to quantize.
Embedding dimensions do not necessarily cooperate.
Information may be distributed unevenly across dimensions, and dimensions that interact strongly may end up split across separate groups.
Optimized Product Quantization addresses this by learning a transformation-often understood as a rotation of the vector space-before PQ is applied. The goal is to find a representation in which the resulting subspaces can be quantized with lower distortion. The OPQ work explicitly optimizes both the space decomposition and quantization codebooks to reduce quantization error.
The intuition is similar to packing furniture into boxes.
PQ says:
“Divide the room into equal sections and pack each section separately.”
OPQ first rotates or rearranges the furniture so that the items fit those boxes better.
Nothing about the semantic meaning of the vector has changed. The representation has been transformed into a geometry that compresses more efficiently.
Current Faiss guidance continues to expose OPQ combined with PQ when memory pressure is high.
IVF-PQ: two approximations working together
IVF and PQ are commonly combined because they solve complementary problems.
IVF answers:
“Which part of the corpus should I examine?”
PQ answers:
“How cheaply can I compare the candidates inside that part?”
The path becomes:
query
  ↓
find nearest IVF centroids
  ↓
open nprobe inverted lists
  ↓
scan compact PQ codes
  ↓
keep best approximate candidates
  ↓
optionally refine using higher-precision vectors
This can reduce both the number of vectors examined and the bytes moved for each vector examined.
Many IVF-PQ implementations improve compression further by encoding the residual rather than the original vector.
If vector x belongs to IVF centroid c, define:
r = x - c
Instead of PQ-compressing x, the system compresses the residual r.
Why?
Because the coarse centroid already explains part of the vector’s location.
Think of describing where a house is.
Instead of storing its full global coordinates repeatedly, first say:
“The house is in Seattle.”
Then encode only:
“1.2 km east and 0.8 km north of the neighborhood center.”
The residual is typically smaller and more localized than the original coordinate, making it easier to quantize accurately.
Faiss’s IndexIVFPQ follows this coarse-quantizer-plus-PQ pattern, and its documentation distinguishes IVF with flat vectors, scalar quantization, PQ, and additional refinement stages.
The production implication is that the index now has several independent control surfaces.
nprobe determines how much coarse space is searched.
PQ code size determines how much information each compressed vector retains.
The number of candidates retained determines how much uncertainty survives into refinement.
The refinement stage determines how much expensive precision is spent repairing the approximate ranking.
These parameters should not be tuned independently.
A more aggressive PQ configuration may require a larger candidate pool for refinement. Lower nprobe may require deeper refinement but cannot repair candidates from partitions that were never searched. Raising candidate count may improve final recall while increasing network and CPU cost downstream.
This is why tuning an IVF-PQ system one parameter at a time often produces misleading conclusions.
The object you are tuning is the pipeline.
DiskANN: design the graph around storage hierarchy
In one sentence: DiskANN keeps most of the index on cheap SSD storage instead of expensive RAM, using a small compressed guide in memory to make sure each disk trip actually gets you closer to the answer.
Eventually the corpus reaches a point where another question dominates:
What if the full high-quality graph index is simply too expensive to keep in DRAM?
One answer is horizontal scaling.
If one machine holds 100 million vectors, ten machines can hold roughly a billion.
But horizontal scaling introduces shards, replicas, routing, fan-out, coordination, and operational overhead. Sometimes the architecture is buying a distributed system largely because it needs aggregate memory.
DiskANN asks whether some of that state can live on SSD without giving up interactive search latency.
The naive version does not work.
Take an in-memory graph algorithm and memory-map it to disk, and every graph hop can become a random SSD read. If a query requires hundreds of dependent hops, each one waiting for the previous one to reveal where to go next, latency becomes dominated by I/O round trips.
The original DiskANN paper framed the SSD problem precisely this way: the critical challenge is reducing both the number of random SSD accesses and the number of sequential round trips on the query’s critical path.
DiskANN therefore uses a graph called Vamana, whose design differs from HNSW in ways that matter specifically for storage.
Vamana: fewer navigational hops matter when each hop may touch SSD
HNSW uses several hierarchical graph layers.
Vamana instead constructs a single directed graph with bounded degree and intentionally preserves connections that help the graph remain navigable over long distances.
Construction begins from a graph over the dataset and uses a central starting point, approximately the dataset medoid, as a common navigation entry.
For each point being indexed, Vamana runs a greedy search toward that point and collects vertices encountered during the search. It then applies a procedure called RobustPrune to choose a bounded set of neighbors from those candidates. The pruning rule attempts to preserve useful geometric diversity rather than simply keeping the closest R points. Vamana performs multiple construction passes, with its pruning parameter α helping introduce longer-range edges.
The intuition behind RobustPrune is important.
Imagine node A has several possible neighbors:
            B
           /
          /
A -------C---------D

                 E
If B and C both lead in almost the same direction, keeping both may be redundant.
A graph with a fixed degree budget benefits from retaining neighbors that open genuinely different paths through the vector space.
This resembles designing an airline network.
If an airport can support only ten routes, connecting it to ten nearby cities in the same direction is less useful than keeping a mixture of local routes and routes that efficiently reach different regions.
Vamana’s pruning strategy attempts to create a graph with good global navigability while maintaining a bounded out-degree. The original DiskANN work found that this structure required fewer graph hops than the compared graph indexes at targeted recall levels, which matters because a hop on an SSD-resident graph can correspond to another round of storage access.
That is the key algorithmic distinction:
HNSW uses hierarchy to obtain long-range navigation. Vamana uses carefully selected edges in a single graph to reduce the number of hops required to navigate the space.
DiskANN is therefore not “HNSW stored on an SSD.”
Its graph was designed around the economics of storage access.
What DiskANN actually keeps in RAM and on SSD
The original DiskANN architecture combines several ideas.
The Vamana graph and full-precision vectors are stored on SSD.
A much smaller PQ-compressed representation of the vectors is kept in memory.
During search, those compressed vectors help estimate which graph nodes are promising enough to justify fetching their neighborhoods from SSD. The system performs a beam search, expanding several promising graph nodes in parallel so that multiple SSD reads can be issued together instead of serializing every graph hop.
Conceptually:
                         RAM
                ┌──────────────────┐
query ─────────►│ compressed vectors│
                │ + hot graph cache │
                └────────┬─────────┘
                         │
                 choose promising nodes
                         │
                         ▼
                         SSD
                ┌──────────────────┐
                │ Vamana graph     │
                │ full vectors     │
                └────────┬─────────┘
                         │
                  fetch neighborhoods
                         │
                         ▼
                 full-precision refine
This is a much richer design than “move the index to disk.”
The in-memory compressed representation acts as a cheap guide.
The graph minimizes the number of navigational storage hops.
Beam search creates I/O parallelism.
Frequently visited nodes can be cached.
Full-precision coordinates are stored next to graph neighborhoods on disk, allowing accurate reranking of nodes whose pages have already been fetched. The original DiskANN implementation deliberately co-locates this information so that full-precision refinement can often piggyback on I/O that traversal already needed.
The durable lesson is more important than the benchmark number:
DRAM capacity does not have to equal searchable-corpus capacity.
The DiskANN trade moves from memory pressure to I/O pressure
Moving most of the index to SSD doesn't eliminate resource constraints - it just relocates them. For an in-memory graph, the limiting resources are DRAM capacity, memory bandwidth, CPU, and cache behavior. For a disk-oriented graph, a different set of parameters becomes first-class instead: storage latency, queue depth, cache hit rate, beam width, random-read amplification, and how many dependent I/O rounds a single query needs to complete. The original DiskANN work found something worth internalizing here - driving SSDs at their maximum advertised throughput actually increases per-read latency, because queues start backing up under that kind of pressure. If tail latency matters to your system, it has to run below saturation, not at the edge of it.
This is a classic production systems tradeoff: a storage device can advertise enormous IOPS, and that number does not mean your retrieval service should try to consume all of it. Think of a highway rated for 10,000 cars an hour at maximum density - at 9,900 cars an hour, one small disturbance is already enough to create a queue, and travel time stops being predictable. Operating somewhat below theoretical capacity is what actually buys predictable latency, whether that's a highway or an SSD queue.
An Engineer evaluating DiskANN-style serving needs more than one benchmark number to reason about this well. What's actually useful is a set of curves:
text
recall vs SSD reads/query
latency vs beam width
p99 latency vs SSD queue depth
QPS vs cache hit rate
DRAM footprint vs disk amplification
A single "5 ms latency" figure doesn't describe the operating surface - these curves do.
FreshDiskANN: static DiskANN is not enough for agent memory
The original DiskANN architecture primarily addressed the large, mostly static index problem.
Agentic systems raise a harder requirement: the corpus may never stop changing.
A graph stored primarily on SSD is expensive to update naïvely because inserting or deleting a point can require changes to graph connectivity scattered across storage.
FreshDiskANN extended the DiskANN line specifically to support streaming insertions, deletions, and searches. Microsoft reports that its experimental system handled a billion-point index on a workstation with SSD and limited memory while supporting thousands of concurrent real-time inserts, deletes, and searches per second and maintaining greater than 95% 5-recall@5 in the evaluated setting.
Again, the benchmark number is not the architectural lesson.
The lesson is that freshness requires a different graph-maintenance design from static search.
A graph optimized once and never changed is a fundamentally easier system than one being mutated continuously while p99 search latency remains bounded.
FreshDiskANN includes explicit update rules and lazy deletion mechanisms rather than simply rebuilding the entire static index after every set of changes.
This becomes a crucial distinction when comparing index families.
Do not ask only:
“Does this index support inserts?”
Ask:
“What physical work does an insert trigger, what structures become temporarily inconsistent, how does that work compete with search, and when does the new vector become searchable?”
That is the connection between ANN selection and the searchable-visibility contract defined earlier in the chapter.
Build time is part of the index architecture
All of these index structures have a construction lifecycle, and none of them are free to build. HNSW has to discover and create graph links as each vector is added. IVF has to train centroids before data can be partitioned effectively at all. PQ and OPQ have to learn codebooks - and in OPQ's case, learn the rotation that makes those codebooks work well in the first place. Vamana performs genuinely expensive graph construction, specifically engineered to produce the bounded-degree, navigable structure that disk-based serving depends on.
This means index-build time doesn't belong in deployment tooling as an afterthought - it's part of the architecture itself. Eventually every index has to be rebuilt, and the trigger can be almost anything: a new graph parameter, an embedding migration, a damaged shard, accumulated tombstones, repartitioning, quantizer drift, corruption, regional expansion, or disaster recovery. Whatever the cause, the same sequence follows:
text
index build time
        ↓
replica provisioning time
        ↓
recovery / migration time
If building a production-quality index genuinely takes twelve hours, the architecture around it has to be able to tolerate those twelve hours - and there are a few real ways to do that. Old and new index versions can coexist while the new one comes up. Replicas can be rebuilt one at a time instead of all at once. A mutable delta index can keep serving recent writes while a large immutable base index gets reconstructed in the background. Snapshots can eliminate most of the rebuild work entirely. But one way or another, the architecture has to pay this cost somewhere - it doesn't disappear just because nobody planned for it.
This is exactly why a benchmark reporting only search latency, recall, and index size is incomplete for production selection. There's a fourth number that matters just as much: how long it takes to create or recover a serving-quality index.
The algorithms fail differently under mutation
This is where the mechanical understanding from earlier in this section actually pays off - because each of these four algorithms fails differently once real mutation enters the picture, not just once.
HNSW is incrementally constructed, so individual additions fit naturally into its model on the surface. But every single insertion still requires graph navigation and link maintenance, which means sustained write rates consume the same CPU and memory-bandwidth resources that searches are competing for. IVF makes insertion mechanically simpler once centroids already exist - assign the new vector to its nearest coarse centroid, append it to the corresponding inverted list, done. But repeated inserts progressively skew list sizes, and the trained centroids slowly become a worse description of whatever the corpus has actually turned into. PQ adds one more learned artifact into the mix: its codebooks. New vectors can still be encoded against the existing codebook without issue, but if the embedding distribution shifts substantially, quantization error creeps upward. DiskANN-style structures make SSD capacity economical, but graph updates are considerably more operationally involved than any of the above - which is exactly why FreshDiskANN and the work that followed it exist in the first place.
There is no mutation-free choice among any of these. Every index family carries its own form of maintenance debt, just accumulated in a different place. HNSW's debt shows up as graph updates, deleted nodes, and mounting rebuild pressure. IVF's debt shows up as partition imbalance and centroid drift. PQ's debt shows up as slowly growing quantization distortion. Disk-oriented graph debt shows up across graph maintenance, storage layout, deletion, and compaction all at once.
The practical implication is that a mature serving system can't just monitor whether the index is online. It has to monitor whether the assumptions that made the current configuration a good choice in the first place are still true.
Query shape can matter as much as corpus size
Another reason there is no universal winner is that index performance depends heavily on the shape of the queries hitting it, not just the size of the corpus underneath it. Suppose two systems each hold 500 million vectors. The first receives individual interactive queries that need high recall and sub-50ms latency. The second receives batches of thousands of queries at a time from an offline recommendation pipeline. Same corpus size, completely different optimization opportunities.
Graph traversal is attractive for individual low-latency searches precisely because each query can navigate selectively through a small portion of the index rather than touching everything. IVF/PQ-style scans become attractive under batching for the opposite reason - centroid lookup, list scanning, lookup-table computation, and distance calculations can all run efficiently across large, regular batches, and map naturally onto vectorized or GPU hardware. This isn't theoretical: current Faiss reflects exactly this architectural split. Its IVF and PQ families have GPU implementations, while its HNSW implementation stays CPU-oriented.
That leads to another rule worth internalizing: don't choose an ANN family from dataset size alone. Choose it from dataset size × query shape × update shape × hardware topology. The workload envelope matters more than the raw vector count ever will.
The candidate-generation layer does not need to be semantically perfect
There's a broader implication here for agentic systems specifically. Modern retrieval pipelines increasingly separate candidate generation from semantic judgment - the ANN index is trying to cheaply preserve enough potentially relevant evidence, while a reranker downstream examines the query-document interactions much more carefully. That separation changes how the ANN layer should actually be optimized.
If the reranker needs 40 final candidates, the vector index might retrieve 200. The ANN layer doesn't need to perfectly order those 200 - it just needs the truly relevant documents to survive into that set at all. That reframes what's worth measuring: evaluating Recall@100, Recall@200, and Recall@500 tells you far more about whether the system is working than obsessing over whether the vector index alone perfectly orders its first ten results.
HAKES's recent two-stage design - a highly compressed filtering pass followed by a more accurate refinement stage - is one contemporary example of this same broader architectural principle showing up in real systems. The principle itself is simple to state: spend cheap operations on breadth, and expensive operations on uncertainty. HNSW, IVF, PQ, DiskANN, exact refinement, and neural reranking can all take part in that same hierarchy, each doing the part it's actually good at.
There may not be one index for the entire corpus
Once these mechanics are understood, another assumption falls away: every vector in the application doesn't necessarily need to live under the same ANN policy. Consider an agent platform holding three distinct classes of retrieval data. Long-lived enterprise documentation changes slowly and receives broad semantic queries. Recent agent memory changes continuously and gets queried heavily during active sessions. Historical memory is large, cold, and rarely touched at all. Running one index configuration across all three may be operationally convenient, but it's economically poor - each class wants something different from its index, and forcing them into the same policy means paying for capabilities none of them actually need most of the time.
A more sophisticated architecture might keep recent memory in a mutable, memory-resident structure, compact older data into a more storage-efficient index once it cools off, and retain enterprise knowledge in a separate index optimized specifically for high read recall. Conceptually, the query path looks something like this:
                    query
                      ↓
              retrieval coordinator
               ↙      ↓       ↘
          hot memory  knowledge  cold memory
          mutable     stable     compressed /
          in-memory   graph      disk-backed
               ↘      ↓       ↙
                   merge
                     ↓
                  rerank
This is closely related to LSM-tree thinking in traditional storage systems - the representation optimized for ingest doesn't have to be the same representation optimized for long-term search, and trying to make one structure do both jobs well is usually where the compromise shows up. Later sections on the write path and compaction develop this idea further.
The important point here is that "which ANN index do we use?" may itself be the wrong architectural question to start with. The right answer often depends less on the algorithm and more on the lifecycle and temperature of the data sitting underneath it.
The decision is an operating surface, not a leaderboard
Imagine benchmarking four configurations side by side. HNSW produces excellent latency and recall on a static, read-only index. IVF-PQ uses a tenth of the memory but needs more candidate refinement to compensate. DiskANN uses far less DRAM but introduces SSD I/O directly into the tail latency. A hybrid configuration adds extra stages but holds onto higher throughput. Picking whichever one has the best Recall@10 at a single query rate misses the actual production question entirely.
Now introduce realistic conditions on top of that benchmark, one at a time. Double the query concurrency. Run production ingestion at the same time as the search traffic. Apply the most selective authorization filter the system will ever see, then apply the broadest one. Warm the cache, then deliberately destroy locality. Let a realistic amount of deleted data accumulate. Rebuild another shard concurrently. Lose a replica. Shift from today's corpus distribution to the one you expect twelve months from now. Run the same four configurations through all of that, and the ranking can change completely - sometimes the winner on the clean benchmark isn't even competitive once real conditions show up.
What the architecture actually needs isn't a winning point on a chart. It needs to stay inside an acceptable operating region across everything that workload envelope throws at it - a region defined by a handful of hard boundaries at once: a recall floor, a p99 latency ceiling, a memory budget, an ingestion target, a searchable-visibility SLO, and a recovery objective. The winning index isn't the one that tops any single benchmark chart. It's whichever architecture stays inside all of those boundaries simultaneously, across the workload the system will actually see - not the workload it happened to be benchmarked on.
Here's how the specific mechanisms actually behave against the dimensions that matter most for staying inside that region:
| Recall-vs-throughput (static, in-memory, uncontended) | Memory footprint | Build time | Behavior when the index is being written to while serving queries | Read-time latency when many queries compete for disk I/O | Precision lost to compression | |
|---|---|---|---|---|---|---|
| HNSW | Best or near-best - this is exactly why it's the default choice for most people | Highest of this group - production reports of 100+ GB are common at scale | Longest to build | Weak - graph link maintenance and lock contention under sustained writes | N/A - fully in-memory, no disk trip during search | None - stores full-precision vectors |
| IVF (plain / "IVF-Flat") | Lower than HNSW at matched settings, but the loss here is purely from not searching every cluster - no compression involved | High - still stores full-precision vectors, just sorted into lists | Fast - just clustering to find centroids, far cheaper than graph construction | Weak - centroids get trained once and slowly stop matching the data as it drifts | N/A - in-memory | None - same reason as above |
| PQ / OPQ (a compression layer, not a standalone search structure) | N/A on its own - PQ compresses vectors, it doesn't decide which ones to compare; it's always paired with something else | Dramatically reduced - this is the entire point of PQ | Needs to build its codebooks (and for OPQ, a rotation step) before anything can be encoded | Codebooks can go stale the same way centroids do, if the data shifts enough | N/A on its own | This is the real cost of PQ - OPQ exists specifically to shrink this loss below what plain PQ leaves behind |
| IVF-PQ (the common production pairing) | Lower than HNSW at matched settings; a refinement stage added on top closes most of the gap | Low - an order of magnitude smaller than HNSW, this is the whole selling point | Fast | Weak on two fronts at once - both centroid drift and codebook staleness | N/A - in-memory | Yes, inherited from PQ - this is why quantization is usually paired with a refinement stage |
| DiskANN (built on the Vamana graph algorithm) | Comparable to HNSW at rest | Low - by design, most of the index lives on SSD instead of RAM | Moderate-to-long - Vamana deliberately builds a bounded-degree graph (every node capped at the same number of connections, which keeps navigation predictable) suited to disk serving | Static DiskANN specifically struggles here - this is the whole reason FreshDiskANN exists | The established weak point - SSD queues saturate under concurrent load, and per-read latency climbs as queues back up | Uses a compressed in-memory guide plus a full-precision pass from disk - so the final answer ends up full-precision, at the cost of I/O |
| FreshDiskANN | Same ballpark as DiskANN once caught up | Same as DiskANN | Same as DiskANN | Improved - this variant exists specifically to make streaming inserts and deletes viable without a full rebuild | Same disk-bound weak point as DiskANN - this fixes update handling, not I/O contention | Same as DiskANN |
Read across any single row and one mechanism looks attractive. Read down any single column and a different one wins. That's the whole point: HNSW's memory cost only becomes disqualifying once the memory budget boundary is tight enough to bind. IVF-PQ's centroid drift only becomes disqualifying once the corpus moves far enough from what it was trained on. DiskANN's I/O weak point only becomes disqualifying once concurrency pushes queue depth into saturation. None of these are universal weaknesses - they're conditional ones, and which condition actually binds depends entirely on the specific operating point your system lives at.
The best index is always conditional on the operating point - and production never stops moving that operating point.
A useful way to remember the four mechanisms
Everything covered in this section - HNSW, IVF, PQ, OPQ, IVF-PQ, Vamana, DiskANN, and FreshDiskANN - reduces to four architectural strategies, each attacking the same bottleneck from a different angle rather than competing to solve it the same way. IVF-PQ isn't a fifth strategy - it's the first two combined, exactly as covered earlier. Vamana is the specific graph algorithm DiskANN is built on, so it belongs to the DiskANN row here, not a separate one. FreshDiskANN is the streaming variant of DiskANN - same row, same mechanism, extended to handle continuous updates.
| Mechanism | The question it's asking | What it spends |
|---|---|---|
| HNSW | Can I build enough useful roads that the query navigates to the right neighborhood without visiting the rest of the map? | Graph memory, graph quality, traversal breadth, memory bandwidth |
| IVF | Can I divide the map into regions and open only the regions likely to contain the destination? | Partition quality, nprobe, how much of the population gets scanned, distribution stability |
| Product quantization | Can I represent each location approximately enough that I can compare far more candidates for the same memory bandwidth? | Code size, quantization distortion, candidate recall, refinement cost |
| DiskANN (built on Vamana; FreshDiskANN is its streaming variant) | Can I design navigation so that most of the searchable corpus lives on slower, cheaper storage without putting too many I/O round trips on the critical path? | DRAM footprint, graph hops, beam width, SSD reads, cache locality, update complexity |
Seen this way, these are four alternative answers to the same underlying problem, not four sequential stages a query passes through one after another:
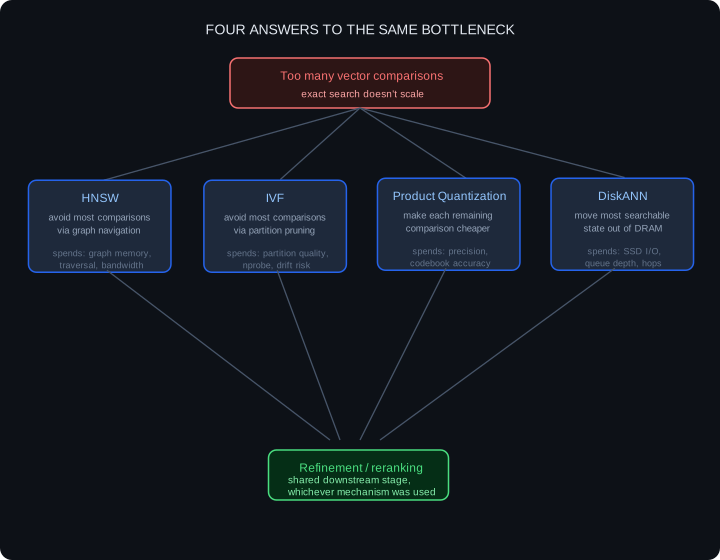
Figure 3-2: Four Answers to the Same Bottleneck HNSW, IVF, and product quantization each attack "too many vector comparisons" differently. DiskANN combines graph navigation with quantization rather than inventing a fifth approach. All four feed into the same downstream refinement stage - but a production system picks one path, or a specific combination.
And production systems are free to combine them rather than pick just one. An IVF system can use HNSW to route among its centroids. IVF can store PQ-compressed residuals instead of full-precision vectors. DiskANN itself already does this - it uses PQ-compressed vectors in memory specifically to guide an SSD-resident graph. This composability is probably the single most important thing for a newer engineer to internalize here: "HNSW versus IVF versus PQ versus DiskANN" is a useful frame for learning the mechanisms individually. It's not how a real production architecture actually gets assembled - that's almost always some combination of them, each handling the part it's genuinely good at.
What an Engineer is actually choosing
At this level, ANN selection stops being primarily an algorithm question. What's actually being decided is where the system will tolerate approximation, which resource ends up absorbing the cost of recovering whatever recall that approximation gives up, and how expensive it will be to change your mind later once the corpus and traffic have grown around that decision.
An HNSW-heavy architecture buys excellent interactive recall by spending DRAM and memory bandwidth. An IVF-PQ architecture buys density and GPU-friendly throughput by spending some partition and quantization accuracy up front, then recovering part of that loss through broader probing and a refinement stage. A DiskANN-style design buys dramatically higher vector density per machine by pushing the corpus down the storage hierarchy - at the cost of making SSD behavior, caching, beam search, and graph maintenance part of the serving SLO instead of someone else's problem. A hybrid system does all of this deliberately, placing different approximations at different stages on purpose rather than picking one mechanism and living with its single tradeoff everywhere.
The architecture is worth judging against five questions, every time: where can relevant evidence disappear? Which knob increases the probability of preserving it? What resource does turning that knob actually consume? What happens while the index is changing, not just while it's sitting static? And how long does it take to rebuild or replace the structure once its underlying assumptions stop being true?
If those five questions have explicit answers for your system, ANN selection is an engineering decision. If they don't, it's leaderboard shopping.
Data placement, routing, replication, and topology evolution
PLACEHOLDER - sharding strategies (tenant/hash/semantic), hot-shard mitigation, replica placement vs. sharding as distinct concerns, online rebalancing, partial-result semantics under failure. Hospital-routing analogy.
The write path and searchable visibility
PLACEHOLDER - write states (accepted, durable, embedded, replicated, indexed, compacted), acknowledgment contract, agent read-your-writes problem, WAL, mutable/immutable segments, compute-storage separation, backpressure.
Updates, deletions, index aging, and non-model migrations
PLACEHOLDER - tombstones, compaction, index aging as a quality problem not just a storage problem, Ghost Vectors research (properly calibrated), logical invisibility vs. physical erasure, brief subsection on non-model migrations (index params, quantization scheme, schema) with cross-reference to Chapter 2 for embedding-model migrations.
Filtered search as adaptive query planning
PLACEHOLDER - pre-filter vs. post-filter vs. iterative filtering as selectivity-driven execution strategies, authorization predicates as trusted-infrastructure-only, graph navigation vs. result eligibility distinction.
Multi-tenant isolation, authorization, and noisy-neighbor control
PLACEHOLDER - opens with: the LLM/agent/reranker is never an authorization boundary. Shared index vs. tenant-aware shards vs. dedicated indexes vs. dedicated deployments. Tiered tenancy. Quotas and admission control.
Semantic observability, failure testing, and operational readiness
PLACEHOLDER - infrastructure telemetry vs. semantic telemetry (mirrors Ch2's vital-signs framing). Production verification checklist. Closes by returning to the Section 1 contract.
Next: Chapter 4 - Chunking, Context Construction, and Document Pipelines